Joseph Machado @startdataeng
Data stuff Free Data Engineering Fundamentals Course: https://t.co/Sp4qDLRwEB startdataengineering.com New york Joined April 2020-
Tweets2K
-
Followers9K
-
Following31
-
Likes621
LLM code generation dramatically speeds up development until it doesn’t. If you’ve worked with AI-generated code, you’ve likely seen: * Bugs are buried in AI spaghetti code that takes longer to fix than it does to write it yourself. * Code that does something completely different than what you wanted This post shows you how to prevent that. You’ll learn to specify requirements, so LLMs generate exactly what you need. And avoid wading through thousands of lines of code to verify correctness. startdataengineering.com/post/using-llm… #dataengineering #llm #codegeneration
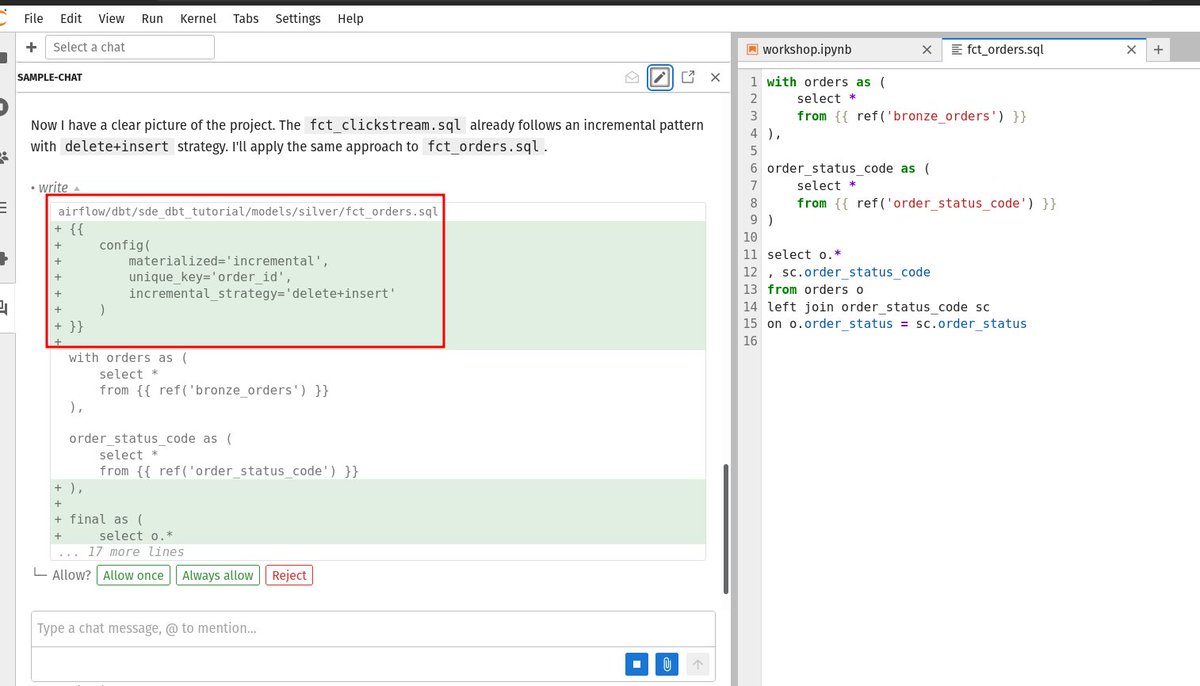
AI makes some reasonable guesses, but always verify the results. I’m working on an article to streamline pipeline creation. We still need humans in the loop. The image below recommends an ID-based delete-insert for a fact table, which will take forever to run if your data is large. Add these to your skills.md file. #dataengineering #llm
“I recommend this to everyone on linkedin asking "what to study" for data engineering. because the topics are so fundamental and work with literally every system (databricks, snowflake, redshift, bigquery, etc)” - One of the comments I got about my Design Patterns workshop Check it out here youtu.be/AXtcWgvCUtw?t=… #dataengineering #pipelinedesign
@Tech_p001 Fair question. We need to review as we would human generated code.
Working on a project that teaches you how to build data pipelines following standard design practices and speeding up development with agent harness & skills! #dataengineering #dataproject

There are a lot of data projects available on the web. While these projects are great, starting from scratch to build your data project can be challenging. If you are wondering how to go from an idea to a production-ready data pipeline This post is for you! In it, we will go over how to build a data project step-by-step from scratch. By the end of this post, you will be able to quickly create data projects for any use case and see how the different parts of data systems work together. startdataengineering.com/post/de-proj-s… #dataengineering #datapipeline
I’ve spent way too much time thinking about my brand colors. Ultimately, I decided to go with what would make my readers' lives easier. A bright screen makes it hard to concentrate for long intervals. So I switched my website to use the Gruvbox theme. Does it help? Check it out at startdataengineering.com

In the past few years, data modeling has gone from “well-planned data model” to “dump everything in S3 and get some data for the end-user”. How do you ensure data correctness when data is expected immediately, and there isn't enough time to get the model right? For solutions, read this startdataengineering.com/post/deliver-d… #dataengineering #datamodel
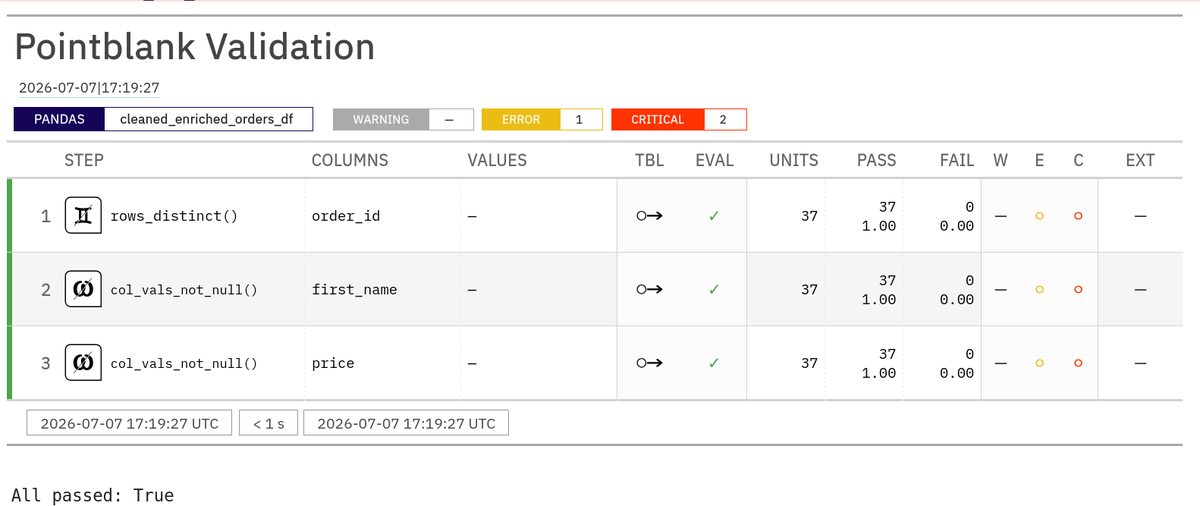
Updating my “Python Essentials for Data Engineers” post and came across this amazing data quality tool. pointblank from posit. Easy to set up and use, as any tool should be. No need to wrestle with 100s of configs/settings. #dataengineering #python #dataquality
One of the biggest causes of data completeness issues is not knowing whether your input datasets are complete. If you schedule pipelines guess when your upstream data may be ready, its hope driven. Learn how to use data asset-based triggers & start your pipelines when the inputs are ready. startdataengineering.com/post/airflow-t… #dataengineering #datapipeline #apacheairflow
Which one should I use; Gruvbox or standard? Gruvbox is easier on the eyes But the standard theme (Bootswatch, Flatly) is familiar Let me know in the poll below 👇 #ux #readability

There are many data projects available online. While these projects are great, starting from scratch to build your data project can be challenging. If you are * Wondering how to go from an idea to a production-ready data pipeline * Feeling overwhelmed by how all the parts of a data system fit together * Unsure whether the pipelines you build are up to industry-standard If so, this post is for you! In it, we will go over how to build a data project from scratch, step by step. By the end of this post, you will be able to quickly create data projects for any use case and see how the different parts of data systems work together. startdataengineering.com/post/de-proj-s… #dataengineering #dataprojects
Using AI for development? Go read @htmx_org ‘ s post. htmx.org/essays/working… Take notes. My experience closely resembles his when building data stuff. 1. AI is good at debugging (only if we have sufficient logs & trace). 2. AI is great at creating tests (although I usually have to specify additional test cases). 3. AI will “sometimes” lead you down a complexity trap when implementing new features. When designing new features/interfaces, I always * Create my own plan with a clear objective and pseudocode * Then review it with AI and iterate. I found this to be much more time efficient and less burnout-y #dataengineering #aidevelopment
When choosing a tool/framework, always pick the one with the simplest implementation. But that could be extended with libraries, Plugins, Ecosystem, etc. Here are some of my favorite tools 1. DuckDB: SQL, enhanced with extensions 2. Python: English-like syntax, enhanced with libraries 3. Quarto: Markdown-like syntax, enhanced with extensions 4. nvim: vim syntax, enhanced with extensions The fancier/esoteric the tool, the harder it is to get productive quickly. What are some of your favorite tools? #tools #dataengineering
This is part of my free data design pattern workshop (next Sat), where I cover this with exercises & arguments. Come join me, sign up here to get notified: startdataengineering.com/newsletter.
90% of all facts and dimensions follow a similar design pattern, with some differences in business logic. This messy middle (fact & dims) is where DEs can lay the foundations for reliable data. If you mess this up, your team will always face issues/questions/mismatches, etc. Here is a V1 of this design

Whenever I design a workshop, I use @robfitz ’s “The Workshop Survival Guide”. I see how great user design increases engagement, recommendations, and leads to higher ratings. Here is a very rough version of a workshop that I am working on (coming soon). Focus on 1. Takeaways for the audience. Not just watch and forget. 2. Increase play. Interweave code exercises and visuals to help understanding. #dataengineering #userexperience

Darshil | Data Engine... @parmardarshil07
32K Followers 745 Following Data Engineer • Founder @thedatavidhya • YouTube (200K+) • Making data easier for everyone
Ergest Xheblati @ergestx
8K Followers 983 Following unlocking inherent potential in people and organizations
SeattleDataGuy @SeattleDataGuy
25K Followers 8K Following Data Engineer/Data Science Consultant and All Around Data Guy | Angel Investor - Now In Denver https://t.co/KZ9mVAg37v
Mim @mim_djo
13K Followers 3K Following #MicrosofFabric user advocate, interests in Small Data & Self Service #Microsoftemployee since Dec 2023 , but my tweets are my own
Rahul Jain @rahulj51
5K Followers 2K Following Engineering Manager, AI Data Products. Formerly led Data and Engineering at @thebeatapp , @omioglobal , @thoughtworks .
Michael Kahan @kahandata
696 Followers 38 Following Helping data teams build reliable modern architectures | Former corporate employee turned independent consultant
Jacob Matson @matsonj
9K Followers 2K Following excel user & data enthusiast. living the dream at MotherDuck
Simon Späti 🏔️ @sspaeti
6K Followers 2K Following Crafting data engineering+ stories. Educator at @sspdatahq & https://t.co/7r8pihWPQz. Dad, Technical Author, Data Engineer. Obsidian & Neovim. Learning for Life.
Modern Data Stack @moderndatastack
6K Followers 439 Following Everything that you need to know about building and operating a Modern Data Stack. Operated by team at @quantive_inc
Anna Geller @anna__geller
2K Followers 429 Following Data & Writing. Product Lead @ kestra Fan of long walks & movies https://t.co/xQE8loTLv8 https://t.co/qohytZQkSn
Alex Monahan @__AlexMonahan__
4K Followers 853 Following Developer Advocate at MotherDuck! Views expressed are my own and not my employer's.
Awani @AwaniAleroA
2K Followers 781 Following DevOps Engineer | Imole De | Owo Oluwa M’be L’ori Aiye Mi | toute gloire à Dieu | Technical Writer @ Rackspace Spot
Omni Data Engineer Ka... @kai_omni
2K Followers 579 Following AZURE Data Engineer | ETL Developer | Web Scraper
Dipankar Mazumdar @Dipankartnt
2K Followers 577 Following director, developers (data/ai) @cloudera, prev @onehouseHQ, @dremio, @qlik, @otisElevatorCo | author of “Engineering Lakehouses” : https://t.co/4xSkn6zskp
b bennett | 500+ conn... @thebmbennett
5K Followers 4K Following data director @workingfamilies prev: @sunrisemvmt. waffle house ambassador & David Byrne fan account. budding organizer. she/her, born n raised on a holler

Halen Hell @halen_hell
0 Followers 291 Following

Rahul GT @_rahulgt
5 Followers 77 Following
Abdo shehata @abdo_shehata1
1 Followers 86 Following A student at the University of Sadat City, Faculty of Computers and AI. "Interested in tech content"
Festim Bunjaku @fbu0514
1 Followers 139 Following

ATIplus @AtIplus
21 Followers 127 Following Paste any sheet → ATI+ detects column types, creates the Azure table & loads your data. No scripting. No setup. Just paste and go. Free on Microsoft Store
El-Hüssieny S. @el7usienysabry
375 Followers 217 Following I don’t think i ll every tell anyone the full story
Apostate @darth_vardhan
15 Followers 176 Following

Gaurav Pal @GauravP67019763
0 Followers 9 Following
ab06 @abo6_pvt
4 Followers 71 Following

Brayan Garzon @elpochch
0 Followers 6 Following

Isaac | Frontier @Isaacjohn_DE
855 Followers 1K Following Data Engineer || ETL Developer Building and sharing what actually works ⚙️ SQL • Python • PySpark • Databricks • Azure
Ralph A Garrett, Jr. @RalphGarrettJr
397K Followers 431K Following 🙏🏾 | Jesus Christ 1st, Father, Husband, Sonship, Profession Musician! 🎶 | https://t.co/kyLcBLGvs8
Benjamin Bennett Alex... @RealBenjizo
37K Followers 437 Following Analyst | Learn Python & SQL | Author | LinkedIn 200k | Newsletter 350k subs | Open 4 Collabos | SQL Essentials for Data: https://t.co/OVaNhH3eeq
Eric Miguel @EricGiovanniMT
16 Followers 96 Following
Vini @Vinvipvina
1 Followers 38 Following


Neural Jelqing (e/acc... @NeuralJelqing
1 Followers 43 Following Here to Observe, Observeooorrrrrrrrr

George Assaad @gassaadx
96 Followers 3K Following Chronically motivated.📍🇪🇬 🇩🇪 🇿🇦 🇺🇸 • M.S. @UCT_news • B.S. @_ZewailCity_
Sarat Viswanatha @SaratViswanatha
49 Followers 2K Following
Sajeevan Veeriah @VeeriahSajeevan
374 Followers 6K Following Building robots and intelligent systems.
Abel Le @tasuke2k3
95 Followers 5K Following


Bharath Kumar @bharath302408
4 Followers 164 Following
H @mm77081
0 Followers 2K Following
E @EltinayHas10873
0 Followers 193 Following
Pankaj Thakur @whoispankaj
2 Followers 80 Following Working as a Data Engineer. Skilled in PySpark, Python, SQL, Azure Databricks, ADF, Azure Storage, Data Modelling, Data Warehousing, RAG, AI Agent.
Osman Ahmed @osayami_dev
187 Followers 4K Following Content creator , developer and advocate for Linux and FOSS صانع محتوى و مطور ، انشر عن البرمجيات الحرة و مفتوحة المصدر ، لينكس و صناعة البرمجيات
Davi Fati | Senior Da... @DaviFatii
5 Followers 58 Following I'm trying to build something that people will use and that will make me money. 🔲 Open to remote work & freelance projects
// @COOKIESnCANDLES
11 Followers 23 Following
Babu @krishb110
21 Followers 92 Following
conibon @conibon143
1 Followers 65 Following
Nitesh Jangir @NiteshJ51970960
15 Followers 127 Following Building PySematic | https://t.co/ZaHVjyItZ8 | Building Scalable Data Pipelines for Startups & SMEs | AWS, ETL, Spark,SQL

SHASHWATA HALDER @SHASHWATAHALDER
3 Followers 113 Following

Rustan @acewhocares
607 Followers 661 Following Data, cloud, distributed systems. JRPG enjoyer. token fasting
Sylvain Rouxel @Suullyyz
4 Followers 61 Following

Paul Justin Christoph... @TheRealBalen_01
17 Followers 345 Following
Data practionner @amazighski
1 Followers 9 Following documentating my journey in life , data , fitness , lifestyle
Ergest Xheblati @ergestx
8K Followers 983 Following unlocking inherent potential in people and organizations
SeattleDataGuy @SeattleDataGuy
25K Followers 8K Following Data Engineer/Data Science Consultant and All Around Data Guy | Angel Investor - Now In Denver https://t.co/KZ9mVAg37v
Mim @mim_djo
13K Followers 3K Following #MicrosofFabric user advocate, interests in Small Data & Self Service #Microsoftemployee since Dec 2023 , but my tweets are my own
Rahul Jain @rahulj51
5K Followers 2K Following Engineering Manager, AI Data Products. Formerly led Data and Engineering at @thebeatapp , @omioglobal , @thoughtworks .
Michael Kahan @kahandata
696 Followers 38 Following Helping data teams build reliable modern architectures | Former corporate employee turned independent consultant
Simon Späti 🏔️ @sspaeti
6K Followers 2K Following Crafting data engineering+ stories. Educator at @sspdatahq & https://t.co/7r8pihWPQz. Dad, Technical Author, Data Engineer. Obsidian & Neovim. Learning for Life.
Dipankar Mazumdar @Dipankartnt
2K Followers 577 Following director, developers (data/ai) @cloudera, prev @onehouseHQ, @dremio, @qlik, @otisElevatorCo | author of “Engineering Lakehouses” : https://t.co/4xSkn6zskp
Jeremy Howard @jeremyphoward
329K Followers 7K Following 🇦🇺 Co-founder: @AnswerDotAI/@FastDotAI ; Prev: Professor@UQ; @kaggle founding president; founder @fastmail/@enlitic/… https://t.co/16UBFTX7mo
José Valim @josevalim
56K Followers 90 Following Creator of @elixirlang. Chief Adoption Officer at @dashbit, where we build https://t.co/FK8F4URbVG and https://t.co/xncEVrvWml.
Jay Clouse @jayclouse
55K Followers 4K Following Founder of Creator Science — running experiments, interviewing remarkable creators, and studying trust. 🎥 https://t.co/bCJOkU80gw

Cynthia Dunlop @c_a_dunlop
2K Followers 1K Following @scylladb | P99 CONF | Monster Scale Summit | Writing for Developers (https://t.co/BiDg9UfnOF)
John Carmack @ID_AA_Carmack
4.1M Followers 295 Following AGI at Keen Technologies, former CTO Oculus VR, Founder Id Software and Armadillo Aerospace
Austin Kleon @austinkleon
137K Followers 1K Following NYTimes bestselling author of STEAL LIKE AN ARTIST and other books. Subscribe to my weekly newsletter & log off this hellsite: https://t.co/dQIzmsUdAY
the tiny corp @__tinygrad__
83K Followers 204 Following We make tinygrad; sell tinybox for the GPU middle class. Our mission is to commoditize the petaflop.
Mitchell Hashimoto @mitchellh
230K Followers 154 Following Co-founder of @Superlogical. Creator of Ghostty. 👻 Prev founded @HashiCorp, created Vagrant, Terraform, Vault, and others.
Mehdi Ouazza @mehd_io
3K Followers 697 Following 🥑 DevRel @motherduck (Cloud-based DuckDB) ✍️ 🎥 Teach about data, AI, software engineering
Derek Sivers @sivers
286K Followers 9K Following Author, explorer, xenophile, programmer, netizen, conversationalist. Former musician and entrepreneur. Everything is at https://t.co/fuY6AJRuz5

Rob Fitzpatrick 📚 @robfitz
17K Followers 636 Following 14 years running little businesses and 3 books about my learnings along the way. Tweets about the career path of entrepreneurship & the business of indie books.

htmx.org / CEO of htm... @htmx_org
59K Followers 332 Following high power tools for html - ʕ •ᴥ•ʔ made in montana https://t.co/P2PXneoQpa (u know u want some) idk!
Jason Cohen @asmartbear
49K Followers 739 Following Keyword, buzzword, half-truth, adjective, hey look at me! (𝘧𝘰𝘶𝘯𝘥𝘦𝘳 𝘰𝘧 𝘵𝘸𝘰 𝘶𝘯𝘪𝘤𝘰𝘳𝘯𝘴: https://t.co/Cc4OvZx0T9, https://t.co/JTEGCe7Zq6)
Ananth Packkildurai @ananthdurai
3K Followers 2K Following Data @Zendesk, @SlackHQ | Author https://t.co/rvlBOXXy26 | Creator of https://t.co/XdMVrxUInE
Axel Kee 🐐🇲🇾 @soulchildpls
2K Followers 3K Following I like to make simple helpful apps. Learn how to customize your Shopify store without coding knowledge : https://t.co/vZI65P5RF4 John 8:7
Bob Haffner @bobhaffner
289 Followers 111 Following Data Engineer | Host of @EngSideOfData #dataengineering #dataengineer podcast: https://t.co/07UIkRSRci
Neelesh Salian 💻 @nssalian
2K Followers 69 Following Software Engineer. Opinions and views shared here are my own. Most posts are jokes. I post about things related to data and tennis.
Pete Hunt 🚁 @floydophone
36K Followers 973 Following Dad Frameworks @Vercel Prev: Dagster, Twitter, Excalidraw, Smyte, Instagram, Facebook, React.js
📙 Alex Hillman @alexhillman
15K Followers 720 Following one of the first ~8,000 people on this site, somehow. left. now i'm back and working on @jfdibot to help me run my community, businesses, and more. ai mechanic.
Nick Maggiulli @dollarsanddata
190K Followers 423 Following Helping people build wealth since 2017. Author of Just Keep Buying (https://t.co/8gu4qZ7MWy) & The Wealth Ladder (https://t.co/3lGb0qPuin)You might like