

Runhan Huang @RunhanH
PhD student @Harvard | Prev. @Tsinghua_IIIS (Yao Class) | Robot Learning, Generative AI hrh6666.github.io Cambridge, MA Joined September 2024-
Tweets78
-
Followers186
-
Following521
-
Likes1K
wow!! GPT-6 Astra can rapidly adapt to a new robot embodiment and a new task 🤯🤖 We asked it to put a cake into an air fryer in the benchmark we’re building, using simple tool APIs including CuRobo-based motion planning. Its first attempts were chaotic. After repeated interaction, it accumulated environment-specific experience and learned to reliably complete the task end to end. 🍰➡️🔥 This is generalization far beyond VLAs and WAMs.
Remember the car task in the DARPA Robotics Challenge? I asked Astra to tackle getting a humanoid into a Tesla—in Mujoco. Two videos: learning through my feedback, then reusing that experience for direct execution using onboard egocentric perception and in-context adaptation.

We put GPT-6 Astra in the RoboDojo. 🥋🤖 The RoboDojo Team conducted a comprehensive evaluation of GPT-6 Astra as an embodied agent, including: • RoboDojo Sim & Real, compared with GPT-5.5 and DeepSeek-Flash • Humanoid high-level control • Dexterous piano playing with RoboPianist 🎹 • A systematic study of in-context learning (ICL) Our key takeaway: GPT-6 Astra demonstrates remarkably strong semantic and spatial understanding, together with impressive in-context adaptation. At the same time, physical commonsense remains a clear bottleneck — revealing an important gap between understanding the world and truly reasoning about its physics. Full report & demos: robodojo-benchmark.com/report/gpt-6-a… @_wenbozhang (project lead), @wenhaocha1, @frankzydou, @JinWeiyang18434, @YutaoOuyang, @minifullcapsule, @x_h_ucb, @YutaoOuyang, @YueChen614

Introducing Hypit: Clone any viral video with AI agents. 1 clone, 100 variants, 100M views. Hypit lets your AI agent (Claude Code, Codex...) clone any viral video. Paste any viral video link from TikTok, Instagram, or YouTube into your agent. Hypit clones it into a complete agentic video workflow: footage, captions, B-roll, effects. GitHub: github.com/hypit-ai/hypit Key Point: - Arcads: $220 / month - Higgsfield: $129 / month - Creatify: $99 / month - Hypit: FREE 🌟 Build the video creation harness for AI Agents. Redefine how videos are made. Like + comment "Hypit" and I' ll send you 100 free AI avatars, each with its own unique voice. And if you like what we’re building, give Hypit a 🌟 on GitHub.

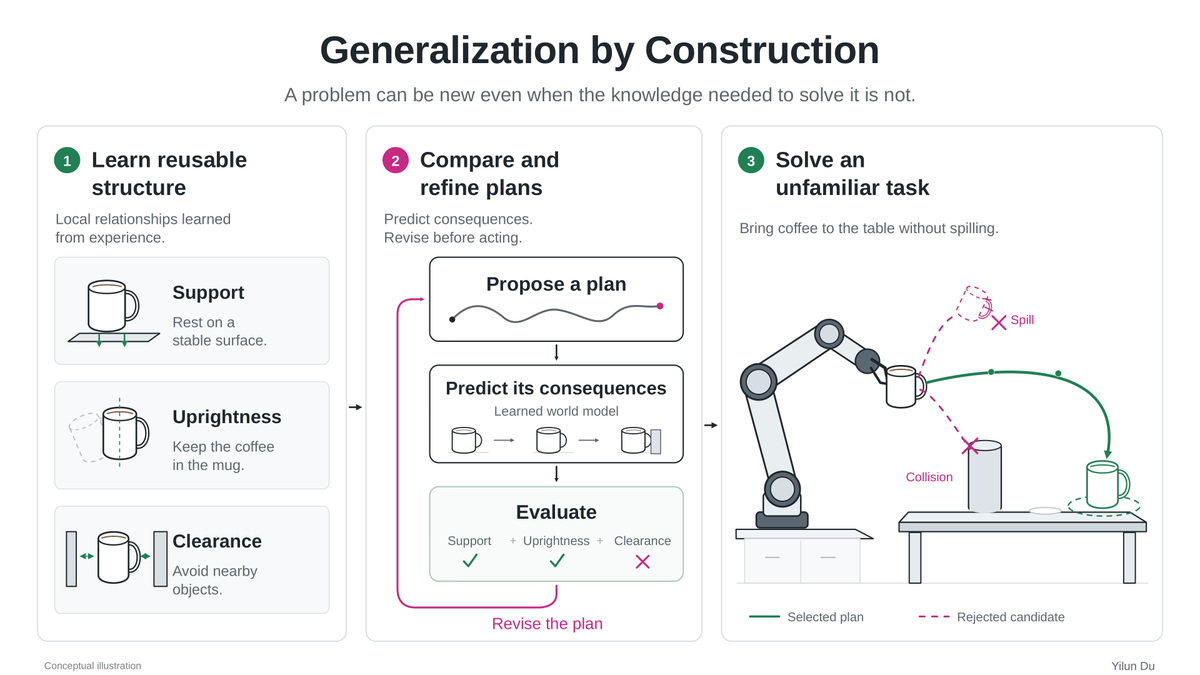
How can we improve robot generalization beyond collecting more demonstrations? A robot can use inference to work out how to solve tasks it was never explicitly trained to perform. With learned models of the world, we can plan our future actions and goals before acting. I wrote a research perspective, Generalization by Construction, on how learning can be combined with inference for flexible generalization. yilundu.github.io/perspective/ge…

🤖 World Action Models predict the future to act better. However, WAM research remains fragmented in code, ad hoc in design, and unprincipled at scale. 💡 Today, we release 𝗢𝗽𝗲𝗻𝗪𝗔𝗠: 𝗔𝗻 𝗢𝗽𝗲𝗻, 𝗠𝗼𝗱𝘂𝗹𝗮𝗿 𝗘𝘅𝗽𝗹𝗼𝗿𝗮𝘁𝗶𝗼𝗻 𝗧𝗼𝘄𝗮𝗿𝗱𝘀 𝗦𝘆𝘀𝘁𝗲𝗺𝗮𝘁𝗶𝗰 𝗪𝗼𝗿𝗹𝗱–𝗔𝗰𝘁𝗶𝗼𝗻 𝗠𝗼𝗱𝗲𝗹 𝗣𝗿𝗲𝘁𝗿𝗮𝗶𝗻𝗶𝗻𝗴 to change this. 🌐 openwam-official.github.io 🧵1/14
Fun experiment: what if frontier models were x OOMs faster, y OOMs cheaper, and fit on an edge device? I had GPT-6 Astra control a simulated Go1: 50 Hz joint targets, like an RL policy. Physics paused between calls. 250 inferences → 5 seconds of walking.
@phillip_isola I disagree. You need high control frequency controllers/policies that deal with forces and contacts. If you believe what you said, here is a simple challenge: implement policies for quadruped locomotion e.g.(vision-locomotion.github.io RSS 2021, CoRL 2022) in your favorite LLM and
Here is a follow up. GPT-6 Astra didn't write code to implement a trot gait and use those numbers. But it could well have memorized the raw joint angles of a trot gait and not actually use the robot state feedback. So here is a Go1 climbing stairs. (This is blind locomotion and again physics is paused between inference calls) I have attached my two prompts as well. Back even in 2023, previous works exploit the impressive in-context learning capabilities of GPT-4 and show trajectory level control by seeding with expert trajectories both for locomotion and manipulation. Here are two works: robot-learning.uk/language-model… prompt2walk.github.io Lastly, I have spent/wasted a whole year way back in 2024 with sim2real RL for custom quadruped robots with high gear ratios (because the motors were weak) and non-negligible leg mass. Now in 2026, it is relatively easy to get a RL policy working in the real world on a Unitree Go1 or G1 only because of the mountain of work done by the community on these platforms. Hardware is really hard. So please take the post in the spirit it was written in, the assumption was if inference latency, compute and cost was not a bottleneck.

Fun experiment: what if frontier models were x OOMs faster, y OOMs cheaper, and fit on an edge device? I had GPT-6 Astra control a simulated Go1: 50 Hz joint targets, like an RL policy. Physics paused between calls. 250 inferences → 5 seconds of walking.

I wanted to find whether GPT-6 hits its limit on robot dexterity. So I just gave it two videos, without states or actions, and told it to do real2sim and physical retarget to Wuji hands. Here are the successful physical rollouts — a Rubik's cube, then an egocentric human video.
Excited to share our work accepted to CoRL 2026 @corl_conf ! We present SkillX: Unified Multi-Skill Policy Learning for Humanoid Soccer — a unified policy that enables humanoid robots to learn and compose diverse soccer skills, achieving smooth skill transitions and long-horizon multi-skill behaviors. Project page: [SkillX project page](yzc0731.github.io/SkillX/) Paper: [SkillX: Unified Multi-Skill Policy Learning for Humanoid Soccer (arXiv)](arxiv.org/abs/2609.06718) Video below 👇 #CoRL2026 #RobotLearning #Robotics #AI #EmbodiedAI #HumanoidRobots #Soccer
Behavioral cloning mystery seohong.me/blog/behaviora… I wrote a new blog post about "mysteries" in behavioral cloning that appear with real-world robot data (e.g., overfitting is "good"). I also tried to demystify them and shared my thoughts!


Excited to share SLAMFormer-∞: an Infinite SLAM Transformer for unbounded frontend and backend processing. From monocular RGB alone, it jointly estimates camera trajectories + dense geometry—and scales to a 17 km urban drive. 🧵

We live in a multimodal world. We see, talk, act, and dream. Yet most LLMs still start with language pretraining. Why not train them natively with multimodal I/O from scratch? Because it’s SUPER HARD, adding modalities triggers training instability, design complexity, and often modal competition So what’s the path forward? Introducing: Towards Physics of Multimodal Pretraining (junlinhan.github.io/projects/physi…) We unpack the underlying mechanics of multimodal pretraining across 4 aspects: Knowledge Flow, Modality Synergy, Early Unification, and Recipe.


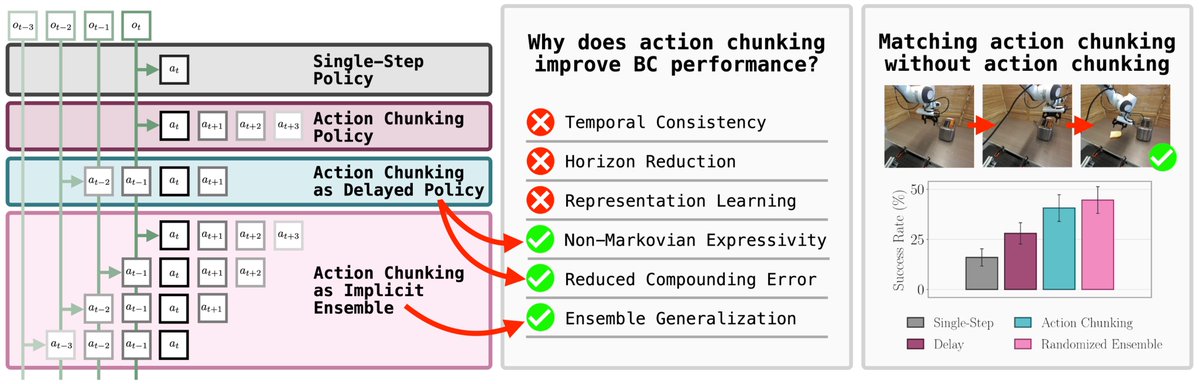
Action chunking is a mysteriously effective method. Modern large-scale imitation learning basically doesn't work without it. But why does it actually help? In our new paper, we try to break down the reasons. As the saying goes, what happened next might surprise you...

Action chunking is a critical component in virtually all modern approaches to imitation learning for robotics. But why is it so critical, and do we really need action chunking? Check out our latest work to find out! (1/n) action-chunking.github.io

Action to action flow matching is a new form of IL, bring faster inference speed. The key question is how much noise do we need in flow matching for multi modality. Human don’t need multimodal decision all the time, e.g., high multimodality when making choice and no multimodality when walking the same way. Then we have MARS policy from A2A, adaptively controlling the noise level. jingliangli.com/MARS_Policy/ Thanks for the podcast by @micoolcho and @chris_j_paxton

Diffusion Policy was one of the big breakthroughs that has enabled an explosion in real-world robot learning. However, it’s always had a weakness, which is that it works by computing a final action trajectory from random noise, which leads to high latency when predicting a final

100K Hours = 4,166.67 days = 11.4 years real-world trajectories 57% success rate on the RoboCasa365 benchmark Maybe we're missing something


Xiaomi-Robotics-1 is now open source!🎉 Xiaomi-Robotics-1 was pre-trained on more than 100,000 hours of UMI data and post-trained with over 10,000 hours of cross-embodiment data. This open-source release covers the complete pipeline from real-robot post-training to model

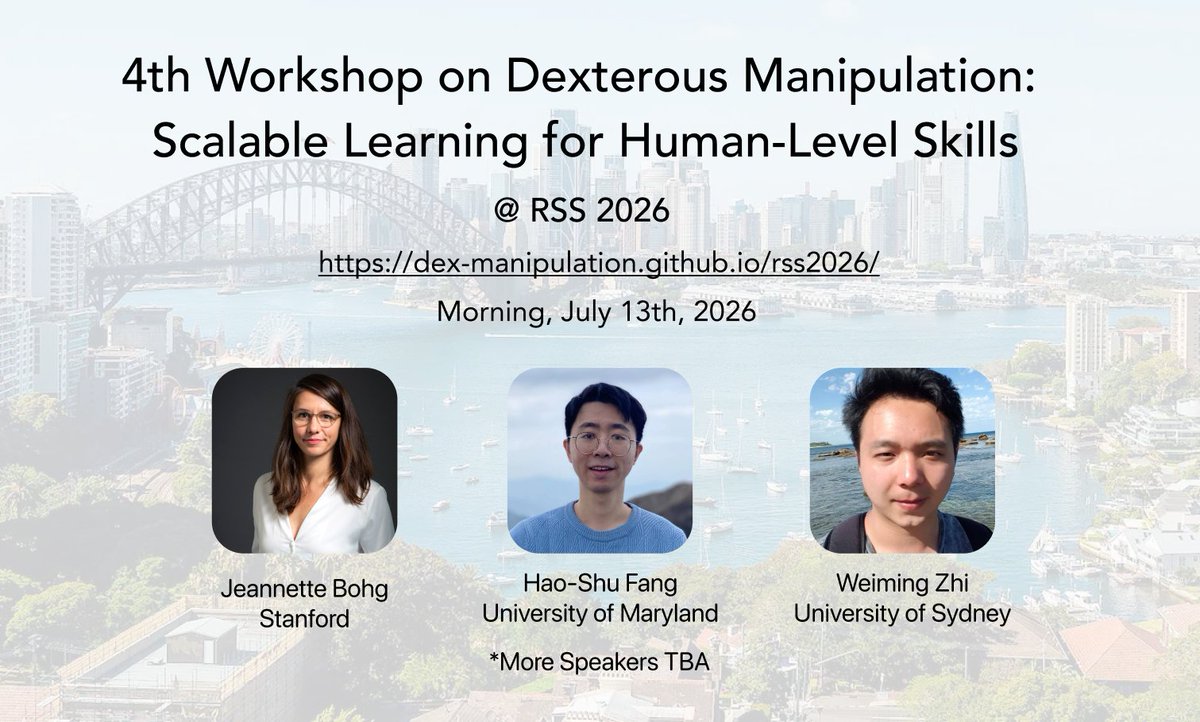
Another belated update: the recording of our RSS 2026 Workshop is now available! Check it out! Huge thanks again to all attendees, speakers, and co-organizers! youtu.be/fN9L5T60I3c
🤖 Excited to announce the 4th Workshop on Dex Manipulation. How time flies! Join us and submit your work to our workshop! Speakers, schedule, call for papers, and more details are available: shorturl.at/APhXq Deadline: June 22, 2026 (AoE) See you in Sydney! #RSS2026

Jason Wang @JasonWang140136
12 Followers 123 Following
Heng Yang @hankyang94
5K Followers 567 Following Assistant Professor @Harvard SEAS @hseas, Lead the Harvard Computational Robotics Lab. #Robotics, #Optimization, #Control, #Vision, #Learning

Prime (Shengqu) Cai @prime_cai
2K Followers 784 Following cs phd @stanford | interned @nvidia, seed | prev. @eth | I work on long context, continual learning, generative models, and infra | opinions are my own
Runpei Dong @RunpeiDong
581 Followers 2K Following Intern @ Amazon FAR | CS PhD student @UofIllinois | Previously @Tsinghua_IIIS and XJTU | robotics & ai
Jayaram Reddy @Jayaram_Reddy10
204 Followers 2K Following PhD student @UTAustin. Working on Robot Learning | Prev RA @NUSingapore | Ex Intern @naverlabseurope | M.S @iiit_hyderabad | BTech @iitmadras
Yuncong Yang @YuncongYY
357 Followers 151 Following Third-year CS PhD student at UMass Amherst, advised by @gan_chuang | Intern @Meta | Ex-Intern @MSFTResearch
Kushal @kushalk_
966 Followers 3K Following Postdoc @MIT_CSAIL | previously: @Cornell @Stanford @IITKgp
Chen Feng @simbaforrest
763 Followers 205 Following Institute Associate Professor at NYU | Co-Director of NYU CREO | Amazon Scholar @Amazon FAR
Hjh @ayhnencac
2 Followers 56 Following
Xiaoyu Fan @ShayueFan
3 Followers 327 Following Undergraduate @HuazhongUST | Interested in Multi-agent systems, AI4Medicine, and MLLM | Opinions are my own
zhaoyu zhu @Zhaoyu_Zhu_
0 Followers 617 Following
andy @andy62832320978
0 Followers 15 Following
Yang @xiaodongyang05
31 Followers 505 Following
warren_hanwen @warren_hanwen
4 Followers 92 Following

Amine ANDAM @AmineAndam
319 Followers 3K Following PhD student @UM6PCC | Adversarial Reinforcement Learning


Roboto @roboto_ai
896 Followers 201 Following Agents that analyze your robotics data, so you know how your robots behave, why they fail, and what to improve. Analytics for Physical AI.
Jingrui Pang @PangJingrui
27 Followers 530 Following 🔬 PhD student@Tsinghua University | 📚 Bridging Brain Science & AI for Exoskeleton Control
Damir Becirovic @damirbecirovic
537 Followers 3K Following Founding Partner @relentless_inv Previously @indexventures
lux @lux_0902
1 Followers 220 Following


Linli Shi @linlishiac
6 Followers 83 Following @JHUECE Focus on Computer Vision, Robotics and Embodied AI
维 @YscbIOxOU0M0F8J
47 Followers 2K Following PhD student @Tsinghua_Uni | Prev. USTC | Intern @Huawei @ByteDanceTalk @MSFTResearch
rita @rita17371931
25 Followers 192 Following Undergraduate student at iiis (yao class) , tsinghua university. Currently interested in ml system, especially distributed training.
Qianqian Wang @QianqianWang5
5K Followers 542 Following Assistant Professor at Harvard University and Kempner Institute
Archi @quejiao
5 Followers 340 Following
pranjal bhatia @praaaanjal
32 Followers 219 Following researching @ purdue. i’m stupid and looking to learn.
knop @XlwlO
1 Followers 48 Following
Weiji Xie @Shi_Soul
69 Followers 591 Following
Alex @alexbryant68
2 Followers 76 Following
qwaszx_Dd @DdQwaszx
0 Followers 1 Following
Weijie Wang @ZiMu983597
10 Followers 301 Following
lodeeo @lodeeoy
7 Followers 2K Following
yixuan_li @yixxuan_li
50 Followers 297 Following Ph.D. student @ BIT. Interested in robot learning, 3D vision.
Fenghua Zhang @coffeeJohnZhang
2 Followers 35 Following
Revant Mahajan @MahajanRevant
178 Followers 2K Following Generalised Robotic Exploration in Real World | M.S. CSE @UCSD | Ex-Software Engineer in Path Planning @AmazonRobotics
JunLi Ren @junli_r84995
344 Followers 269 Following PHD Candidate @HKU MMLab, currently visiting @UCBerkeley , undergrad and master @Tsinghua_Uni.
Mark Landergan @MLandergan
5 Followers 56 Following Robotics Engineer specalizing in Reinforcement Learning
Zhenting Qi @ZhentingQi
1K Followers 740 Following CS PhD @Harvard | Researcher @MetaFAIR @GoogleDeepMind @MIT @MITIBMLab @MSRAsia | Alumni @UofIllinois @ZJU_China
Wenkun He @HeWenkun1228
5 Followers 7 Following
Mengjie Zhao @qxjyqzw
13 Followers 67 Following Third-year junior undergraduate in Institute for Interdisciplinary Information Sciences, Tsinghua University.
Hatem Hassan @HatemHassan686
24 Followers 891 Following Embodied Intelligence, Robot Learning, cognitive Robotics, Causal inference, Motion generation, RL
satyam @satiyum
576 Followers 2K Following data for robotics and health unlock the future we need. founder, https://t.co/ji2txiGF8Q, https://t.co/7eH2e6LVXg, https://t.co/AciEw5Exhq
Dipam Patel 🦾🦿 @_dipam_
22 Followers 1K Following PhD Student in CS, Purdue University. Working on Whole-Body Control for Quadrupeds and Humanoids.
Bingao Chen @bingao_chen
73 Followers 419 Following Undergrad @Tsinghua_Uni | Intern @Stanford | Prev @nyuniversity
Brandon Yifan Yang @brandonyyang02
38 Followers 165 Following Honda Research Institute | Robot + AI Research at @AfterQuery | Robotics at @Penn | Prev at @UVA
Shuyan Zhou @shuyanzh36
5K Followers 799 Following agents @meta superintelligence | prev: assistant prof @dukecompsci, phd @LTIatCMU
Chenhao Li @breadli428
8K Followers 474 Following AI & Robotics @GoogleDeepMind | Doctoral fellow @ETH_AI_Center, @leggedrobotics | Prev. @MIT, @ETH_en, @MPI_IS.
Jacob H. Rothschild @ja_rothschild
1K Followers 26 Following Robot learning | ex-QuantCo | ETH Zurich Statistics MSc
Hanwen Jiang @hanwenjiang1
2K Followers 729 Following Research Scientist @ Adobe Research | PhD @ UT Austin | Exploring what could unlock human productivity: currently visual intelligence, previous 3D (failed)
WUJI @wuji_global
4K Followers 95 Following To provide the physical world infrastructure that accelerates the arrival of general purpose robots. Founder & CEO: @Yunzhe_Pan Email: [email protected]


Lingjun Mao @Lingjun_Mao
122 Followers 91 Following PhD student at @ucsd_cse | Research in VLM & Multimodal Learning | Formerly @BerkeleyNLP
Runpei Dong @RunpeiDong
581 Followers 2K Following Intern @ Amazon FAR | CS PhD student @UofIllinois | Previously @Tsinghua_IIIS and XJTU | robotics & ai
Qineng Wang @qineng_wang
884 Followers 199 Following Second-year PhD student at @NorthwesternU | Advised by Prof. @ManlingLi_ | Research Visit @Stanford | Foundation Models for Embodied Agents 🤖
Qiuyang Mang @MangQiuyang
1K Followers 832 Following PhD student at UC Berkeley @BerkeleySky. Former ICPC World Finalists; Opinions are my own
Alvin Chen @cccyd_qwq
1K Followers 447 Following building @hypitai gonna kill Adobe & capcut & DaVinci building https://t.co/MyKszlLy9I Claude/GPT API platform
Wei-Chiu Ma @weichiuma
2K Followers 223 Following Assistant Professor @Cornell @CornellCIS Prev: Postdoc @allen_ai @uwcse; PhD @MIT_CSAIL; Sr. Research Scientist @UberATG @Waabi_ai
Bidhan Roy @bidhan
4K Followers 976 Following ceo @bageldotcom. building general world model for physical AI.
Zechen Bai @ZechenBai
428 Followers 478 Following CS PhD @NUSingapore ; Previous Meta MSL, AWS, ByteDance; I build multimodal foundation models and agents. I care about data, eval, post-train, and harness.
Kushal @kushalk_
966 Followers 3K Following Postdoc @MIT_CSAIL | previously: @Cornell @Stanford @IITKgp
Jay Chooi @chooi_jeq
9K Followers 193 Following Co-founder, robot benchmarks @robocurve (YC Public Benefit Corp) | Previously at Harvard, Rhodes, UK AISI, MATS
Jiawei Gu @Kuvvius
673 Followers 347 Following
Yuncong Yang @YuncongYY
357 Followers 151 Following Third-year CS PhD student at UMass Amherst, advised by @gan_chuang | Intern @Meta | Ex-Intern @MSFTResearch
Hjh @ayhnencac
2 Followers 56 Following
Chen Feng @simbaforrest
763 Followers 205 Following Institute Associate Professor at NYU | Co-Director of NYU CREO | Amazon Scholar @Amazon FAR

Martin Peticco @martinpeticco
265 Followers 68 Following I build robot manipulation hardware and some software | PhD at MIT, Improbable AI Lab
Justin Chen @ch3njus
267 Followers 2K Following Founder @parkour_company | Parkour Theory | Prev: BA, MS @ Boston University CS
Boris Belousov @_bbelousov
1K Followers 623 Following Curious, intrinsically motivated agent; AI engineer @ stealth startup, Munich; prev senior researcher @DFKI Systems AI for Robot Learning, @ias_tudarmstadt
Jayaram Reddy @Jayaram_Reddy10
204 Followers 2K Following PhD student @UTAustin. Working on Robot Learning | Prev RA @NUSingapore | Ex Intern @naverlabseurope | M.S @iiit_hyderabad | BTech @iitmadras
Amine ANDAM @AmineAndam
319 Followers 3K Following PhD student @UM6PCC | Adversarial Reinforcement Learning
lil’km @_lilkm_
639 Followers 2K Following Robot learning @LeRobotHF @huggingface. Building Physical AI @codecopenflow

Mengjie Zhao @qxjyqzw
13 Followers 67 Following Third-year junior undergraduate in Institute for Interdisciplinary Information Sciences, Tsinghua University.
rita @rita17371931
25 Followers 192 Following Undergraduate student at iiis (yao class) , tsinghua university. Currently interested in ml system, especially distributed training.
维 @YscbIOxOU0M0F8J
47 Followers 2K Following PhD student @Tsinghua_Uni | Prev. USTC | Intern @Huawei @ByteDanceTalk @MSFTResearch
Linli Shi @linlishiac
6 Followers 83 Following @JHUECE Focus on Computer Vision, Robotics and Embodied AI
Damir Becirovic @damirbecirovic
537 Followers 3K Following Founding Partner @relentless_inv Previously @indexventures
Jingrui Pang @PangJingrui
27 Followers 530 Following 🔬 PhD student@Tsinghua University | 📚 Bridging Brain Science & AI for Exoskeleton Control
Roboto @roboto_ai
896 Followers 201 Following Agents that analyze your robotics data, so you know how your robots behave, why they fail, and what to improve. Analytics for Physical AI.
Georgia Chalvatzaki @GeorgiaChal
7K Followers 2K Following Professor @CS_TUDarmstadt, @hessian_AI, AI Emmy Noether @dfg_public, #ERCStG SIREN, #AlfriedKruppFörderpreis, co-chair TC @MobileManip

Yuki Mitsufuji @mittu1204
5K Followers 88 Following PhD, Distinguished Engineer @Sony, Visiting Research Professor @nyuniversity, World's Top 2% Scientist
Weijie Wang @ZiMu983597
10 Followers 301 Following
Revant Mahajan @MahajanRevant
178 Followers 2K Following Generalised Robotic Exploration in Real World | M.S. CSE @UCSD | Ex-Software Engineer in Path Planning @AmazonRoboticsTrends for United States
You might like


















