

OpenTrain AI @OpenTrainAI
The Data Labeling Marketplace | Where AI Builders and AI Trainers Connect to Build the Future | Find, hire, & securely pay data labelers for any annotation tool opentrain.ai Seattle, Washington Joined September 2023-
Tweets23
-
Followers229
-
Following104
-
Likes0
@natolambert They could hire & pay the same talent from these "data foundries" directly on OpenTrain.ai. Savings are often 50%+
@Suhail Here to help! opentrain.ai Post your data labeling project and connect with freelancers and/or data labeling agencies. We also offer a fully-managed solution, where we build your own annotation team and manage the whole process. DMs are also open.
At this point I feel like we understand pretty well what's going on with LLMs: - Outputs are roughly equivalent to kernel smoothing over positional embeddings (arxiv.org/pdf/1908.11775…) - The learned computation model is *probably* bounded by RASP-L (arxiv.org/pdf/2310.16028…) - LLMs learn structure primarily from human generated content (text, images) which is far more structured and predictable than the universe. - LLaMa3 shows us that the higher quality the annotations on the human generated content, the better the LLMs do (10million messages is a lot!) - Multi-turn labeling is currently very expensive and so likely driving the costs of the models. - Right now we're likely bottlenecked not on CPU, or size of data, but number and quality of annotations. So tl;dr. Great at predicting what a human would do or say by averaging in distribution data in the corpus. No emergent generality. Currently bottlenecked by high quality annotated data. @hausdorff_space did I miss anything?

The perfect quote to describe LLMs can be found in a 1946 Jean Cocteau movie -- "Réfléchissez pour moi, je réfléchirai pour vous" (think for me, I will reflect for you). What you get from the model is always a reflection of the training data you put in -- itself a by-product of human thinking.
Learn more about OpenTrain's AI Interviewer here: opentrain.ai/news/ai-powere…
NEW FEATURE: AI Live Chat Interviews: Using GPT-4 to interview, score, and screen job applicants from data labelers/AI trainers. One-on-one interviews, at scale! How It Works: #GPT4

With the power of LLMs, we can now do all of this for you behind-the-scenes and then present an AI Qualification Score. From there, you can get a clear view of who are the most qualified candidates.

Traditionally, selecting who to hire required significant time for: -Viewing applicants' resume -Reading cover letters -Messaging follow up questions -THEN judge if they are a good fit for your specific job
@ylecun We're working on this. Hire & pay data labelers/contributors directly, with only a small transaction fee. But if the resulting dataset will be open sourced, ZERO FEES. OpenTrain.ai
Agreed! But some datasets are just too large/require too much time. This is when many turn to crowdsourcing. The issue with crowdsourcing is it's largely a "black box". You don't get any feedback on issues with the dataset or anomalies. This is becoming even more important as people start building more advanced models. Advanced models require labelers with domain-expertise that is not available through crowdsourcing. Here's the data labeling process we'd recommend: 1) Data scientist/engineer do the initial labeling (10-20 hours recommended) 2) Source & hire INDIVIDUAL data labelers with expertise in your data's domain (on OpenTrain.ai of course 😉) 3) Work closely with the data labelers (daily sync up, open communication channels, etc) This allows for deep understanding of training data, while still being scalable for large datasets.
A big reason for this is the cost of hiring data talent. The big data labeling platforms are prohibitively expenses and openly have a 70% margin (and pay their data labelers poorly). We're working on making it easier & more cost-effective for the open source community to get custom data by allowing people to post a dataset need > Get proposals from freelancers (many of whom also work for the large data providers) > Pay them directly with only a small transaction fee for completed milestones. OpenTrain.ai ...We also wave the transaction fee if the resulting data set will be open sourced
We're working on a solution for this. There are a lot of great tools, like Label Studio, but finding specialized talent to do the actual annotation work can be difficult. With OpenTrain, you post your job and select your labeling software > workers submit proposals > you hire and simply add the workers to your labeling software account. You then pay the talent directly in escrow milestones. Also, if the specialized talent isn't on our platform yet, we recruit them and bring them onboard for your job. We only charge a small % on successful milestone payouts...vs the big data labeling companies who charge a massive markup and long term contracts. We support 20+ data labeling tools and hiring in 110+ countries.
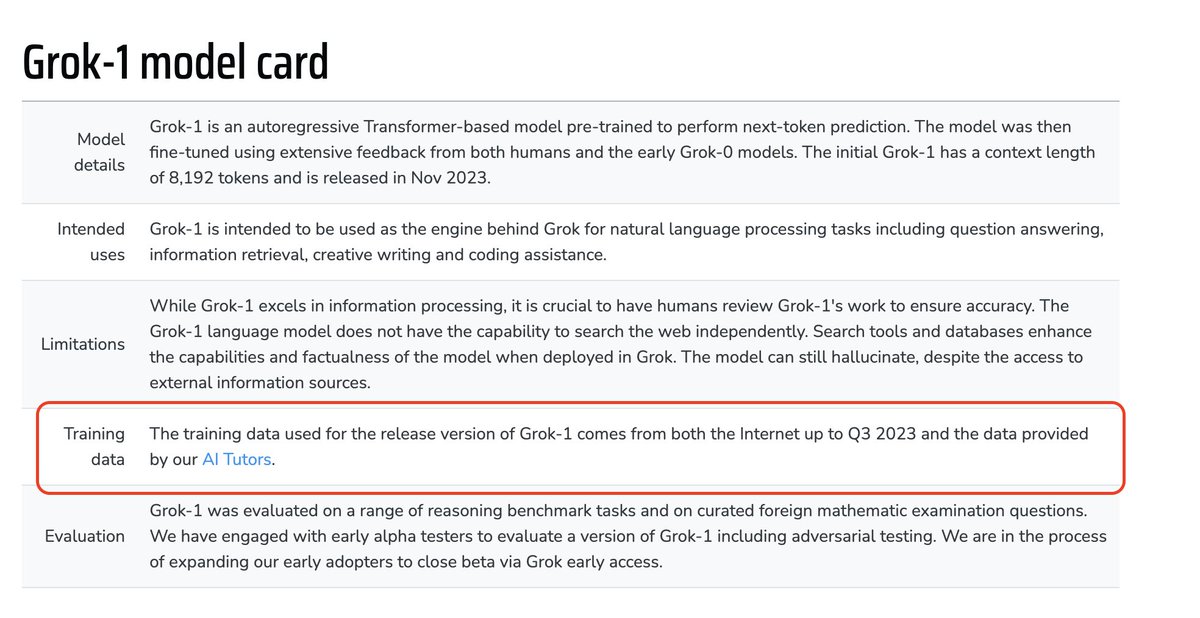
Grok-1 by @xai utilized "AI Tutors", or human subject matter experts to create custom training data & provide RLHF. We're making this easy for anybody to do this with OpenTrain.ai: The data labeling marketplace to find, hire, & pay training data experts for ANY data labeling software. Simply setup the data workflows on your data labeling tool of choice, & use OpenTrain to find the subject matter experts to work from that tool. Like UpWork, but for "AI Tutoring" Post jobs & collect applicants 100% free! #rlhf #llm #datalabeling #trainingdata

🔥Excited to introduce LMSYS-Chat-1M, a large-scale dataset of 1M real-world conversations with 25 cutting-edge LLMs! This dataset, collected from chat.lmsys.org, offers insights into user interactions with LLMs and intriguing use cases. Link: huggingface.co/datasets/lmsys…
An in-depth look at RLHF by @natolambert from @huggingface. The need for high-quality, task-specific data in RLHF is crucial. With OpenTrainAI, you can find, hire, & pay the human experts essential for responsible and effective RLHF. Post your job today! #RLHF #MachineLearning

Reinforcement Learning from Human Feedback (RLHF) is gaining traction. This field aims to make AI more responsible by including human values and preferences. In this video, @natolambert, a research scientist and RLHF team lead at @huggingface explores its inner workings,

Assign Scribe @AssignScribe
126 Followers 686 Following

Cao Tuan Anh | 𝔽rA... @MrDacLong
512 Followers 6K Following Working daily on @Galxe and @MindoAI #Galxe
Wicla @Wicla0020
0 Followers 36 Following
Raymond @itsramyraymie
780 Followers 6K Following
Alberto Contreras @kingoftank
29 Followers 930 Following Aspiro a ser tan grande, que aspiro a ser como yo


Davin YC Dong @DavinYCD
44 Followers 537 Following Founder, Cookiy Labs (@CookiyLabs): a Human Data Layer for research & AI. ex-Meta, TikTok, Alibaba, Tencent. CS PhD dropout @UMich.
Salako Ahmed @ahmed_salako
21 Followers 135 Following Research & M&E | Data Analysis 📊 | Excel | Power BI | MEAL | Building practical research, M&E & data projects | Open to NGO & development roles 🌍

Crowth£r @crowther_a3
2K Followers 2K Following #Web3 Graphic Designer Creative director ≥ @cdsspace_ @cdslabs_ Brand Designer ≥ @houseofwealth_ @shifuwealth #GBPUSD trader https://t.co/ucdz8A1F38…
chege moses @chegemoses77194
0 Followers 2 Following

VAISHNAV @Vaishnavr1k
11 Followers 147 Following
michbolu @MACXTOONS
0 Followers 14 Following


Zy / Human @ziozzzy
562 Followers 3K Following Japan-born. Remote × AI × Japanese. Quietly working on AI training & Japanese-language tasks. Studying neuroscience & psychology. DnB, Survival&craft&build game

kehiñ…de @kennnyy256
170 Followers 1K Following business consultant|| Amazon kdp expert || writer|| MDNI
Prachi @Praachy27
612 Followers 257 Following Surgical Oncopathologist! 🔬An artist by Hobby 🎨a wanderer by passion 🧞♀️ and an explorer by Nature 🍀

Ãdam 🎭 @xAdamAWeb3x
2K Followers 792 Following Community Manager & Moderator • Project Manager @amavie_ai • Helping DAOs, NFT & DeFi grow communities • Trader & Airdrop Farmer • DM for Collab
Angeloedo @edouar8e6
0 Followers 78 Following

Allen Ray @allenray929
0 Followers 23 Following Passionate about connecting with people worldwide, building meaningful friendships, and creating a strong global community that helps make the world a better.
CYPRIAN 🌠 @ChineduNwoko2
15 Followers 89 Following C. Eng👷⚙️🛠️ intended Student of Bells University of Technology, Ota Ogun state
kinyungu njoroge @NjorogeKinyungu
102 Followers 322 Following
Charity | AI Video Cr... @Charity6271
1 Followers 11 Following AI Video Creator | Cinematic AI Visuals | Short-form videos/ads | Image to video | AI Film making | Content Creation |Available for freelance work
Sub Caelo @scbebetterme666
14 Followers 268 Following Theoretical physicist (topological phases & CFT) Language lover.
GaialtairGazeAndDream... @Musatorizuki
266 Followers 5K Following If I discover a form of art I love, I'll retweet and express my admiration with ❤️. You might catch a glimpse of a few pieces from my own illustrations here.
The AI Data Farmer @D8AFarmr
43 Followers 204 Following Visual data provider with decentralized real-time data nodes creating digital twins of the world, measuring traffic, demand, cities, and urban intelligence.
NOPE @DDDON_y
1 Followers 3 Following
CHRIS JOE 🦜 @chris_joe_ai
62 Followers 418 Following Data Annotation Expert | Quality Assurance | Prompt Engineer | AI Trainer | founder of JOVIDER TECH SERVICES 📥 email: [email protected]
Priya Gautam @Priyaaa0409
0 Followers 26 Following
soham kumre @sohamkumre
0 Followers 12 Following
hardy @hathomas000
130 Followers 3K Following

Linus K�... @KirimiLinus
7K Followers 8K Following | 🇰🇪 | Interested in Emerging Innovations in Technology | 🤓 |
R.B.T @the_olamipo
1K Followers 1K Following Crypto Projects || Content shitposter || Degen on the side || Controversial replies || Rabbit cooks — https://t.co/FHvamXgPJ7
LUÍS @LUS8v
0 Followers 1 Following

EMJAY⛓️🎨 @emjaycreative_
256 Followers 411 Following B. Agric || Photographer || Creative Graphics/Brand Artist || Web3 Enthusiast || NFTs || Reply Guy.
Utsuroi♠️ @dweb3creed
156 Followers 319 Following Web3 Community Alchemist | Community Mod |Defi Analyst | Content Marketer for Crypto Brands | Building Engaged Tribes & Alpha Content | Your growth partner💪
TIAN XIA @TIANXIALOVE
0 Followers 44 Following
Larissa Motta @larissamotta_10
5 Followers 99 Following AI Legal Training at the main companies for legal AI training.
Sabashan Ragavan @sabashanR
869 Followers 4K Following Founder & CEO @HeyMiloAI ex-engineer/product @Instagram reels, @Microsoft teams


Eric Glyman @eglyman
377K Followers 2K Following Co-Founder at Ramp (@tryramp). New York City. Previously co-founded Paribus (Acq. by Capital One).
Peter Fenton @peterfenton
49K Followers 1K Following GP @benchmark. Director: @ExaAILabs @mercor_ai @SierraPlatform @ollama @ClickHouseDB @Sorare @sema4ai @airtable @digits @TigerDatabase @LabsCockroach @Docker
Stripe Press @stripepress
35K Followers 73 Following Ideas for progress from @stripe. We publish books about economic and technological advancement.

Derrick Li @TheDerrickLi
2K Followers 6K Following investing @ wildcard . prev @aforevc, @usemacro, altimeter capital .
Sondre Rasch @SRasch
2K Followers 604 Following Co-founder and CEO @SafetyWing (YC18), building a global social safety net. Tweeting about remote work, philosophy, and the future.
Martian @withmartian
4K Followers 14 Following Understanding Intelligence. Measurement. Explanation. Application. That's how we're tackling AI interpretability: the greatest scientific problem of our age.

Harry Stebbings @HarryStebbings
686K Followers 388 Following 🎤 @twentyminutevc, 🏦 @20vcfund, @projecteurope_😇 @fuseenergy @linear @wearelegora @factoryai @lovable @airwallex @mercor_ai @workos @fomo @fireworksAI_HQ


Wispr Flow @WisprFlow
34K Followers 178 Following Smart voice-to-text that turns messy, real-world speech into perfectly formatted text. Now, with Notetaker.
Superpower @superpower
24K Followers 27 Following Live better. A new health system to extend and enhance human life.
Chris Lattner @clattner_llvm
95K Followers 155 Following Building beautiful things like Mojo🔥 and MAX @Modular, lifting the world of production AI/ML software into a new phase of innovation. We’re hiring! 🚀🧠
Ben Wilson @BenWilsonTweets
30K Followers 1K Following I share lessons from history's greatest leaders. Creator and host of @HTTOTW podcast
Parallel Web Systems @p0
22K Followers 57 Following Web infrastructure for AI to search, extract, monitor, and reason over the world's information. Start here → https://t.co/0Enegj3dhv
Ian Ellis @ianellisjones
98K Followers 961 Following @thewarzonewire ⚡︎ @iejmedia ⚡︎ @indopacpodcast ⚡︎ Puncturing the false narratives of adversaries ⚡︎ Subscribe to access the IEJ database⇵ signal: iej.01

Tempo @tempo
90K Followers 1 Following Tempo is the blockchain for stablecoin payments at scale, incubated by @stripe and @paradigm. Live on mainnet.
Marty Kausas @marty_kausas
7K Followers 525 Following ceo @usepylon (agentic support platform) between sf, nyc, london

Vlad Tenev @vladtenev
1.1M Followers 891 Following CEO and Co-Founder @RobinhoodApp 📈📱Executive Chairman and Co-Founder @HarmonicMath 👁️🗨️👨🏫
Mike A. Merrill @Mike_A_Merrill
3K Followers 413 Following Evals at Anthropic, Co-Creator of Terminal Bench, Go Bills
Steven Schwartz 🦅 @cultured
24K Followers 1K Following Co-Founder / CEO @whop - https://t.co/FFEOysAJ6M
scott belsky @scottbelsky
151K Followers 2K Following helping the creative world make ideas happen. partner @a24 / founder A24Labs; founder @Behance, bod @atlassian & MoMA, author, seed investor, product obsessive.


Austin Georgas @AustinGeorgas
8K Followers 144 Following Head of Social @whop | the redbull of entrepreneurship

Keller Cliffton @Keller
24K Followers 742 Following Founder and CEO @Zipline. Previously, built DNA/RNA computers and climbing walls. Harvard grad. Ex-professional rock climber.

Niels Hoven 🐮 @NielsHoven
35K Followers 3K Following Founder and CEO of @MentavaInc. Building early literacy software for preschoolers. Help me bring back excellence in education. Father of 4.

maxleedev @maxleedev
4K Followers 737 Following 19, building consumer | @ucberkeley prev. @interaction and https://t.co/LTjkqY6vTq
Poke @interaction
26K Followers 28 Following Say hi to Poke! The only AI agent verified on Apple Messages 🌴
Bailey @Bruhitsbailey09
19 Followers 90 Following 🤖 AI News & Innovations | 🌐 Artificial Intelligence Trends | 🔍 In-Depth Analysis | 🚀 Future Tech Insights | #AINews #ArtificialIntelligence #TechTrends
CY @LightField
1K Followers 817 Following Run my company w/ 21 AI agents — each with a charter, ledger & sleep. Sharing what actually works, real numbers. Founder @vozoai, 3× Product Hunt · ex-Googler
Adam Silverman (Hirin... @adamsilverman
40K Followers 2K Following Agent Consulting: https://t.co/goijjAdzVD Agent Observability: @AgentOpsAI + https://t.co/JCGSBr6B0L Investing: @theagentfund

Innovatiana @innovatiana
35 Followers 137 Following Need data for your AI? Sure, let random clickers label your brain scans. What could go wrong?🤷 I talk about why 99% of the industry gets AI datasets wrong
roon @tszzl
496K Followers 14K Following “ceterum censeo we must pace the frontier of global machine intelligence progress”
Cameron R. Wolfe, Ph.... @cwolferesearch
41K Followers 842 Following Research @Netflix • Writer @ Deep (Learning) Focus • PhD @optimalab1
Dan Elton 🔍 @moreisdifferent
8K Followers 3K Following Founder and Director of the @MetascienceObs. "Speak your mind, even if your voice shakes". Leave anonymous feedback here: https://t.co/LQ5eZWwDst
Hivemapper @Hivemapper
56K Followers 1K Following We build fresher maps for humanity. Join a decentralized global community of mappers. Earn rewards. (We don't do airdrops, etc. )
LlamaIndex 🦙 @llama_index
121K Followers 38 Following The most accurate agentic OCR platform for production AI. LlamaParse: https://t.co/yQGTiRSNvj Docs: https://t.co/us6GCS1ClbTrends for United States
You might like


















