

vroom vroom @thinkingentity
Joined February 2026-
Tweets68
-
Followers32
-
Following2K
-
Likes1K

My fav YouTube channel has now finished, the first year of Cambridge mathematics for free :)

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI? I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev • 20-200x faster • 40-400x cheaper (w/ output tokens free) • Frontier composable intelligence optimized for decisions AFAICT the shortest path to AI-based economic revolution

Absouloutly fucked this is free.

My list of the best YouTube channels to learn DevOps. 👇

Train your own LLM from scratch! A step-by-step repo that walks you through building and training a transformer model from scratch using PyTorch. From downloading training data all the way to generating text. The architecture is built from the ground up following the original "Attention is All You Need" paper. MLP, single head attention, multi-head attention, transformer blocks, and the full transformer model - all coded and explained with detailed diagrams at each step. Training data comes from The Pile - a diverse 825GB open-source dataset covering books, articles, code, websites, and more. The repo includes scripts to download it, preprocess and tokenize it using tiktoken, store it in HDF5 format, and feed it into training batches. You can train a 13M parameter model on a single Colab T4 GPU. At 13M parameters the model starts generating proper grammar and coherent short sentences. For billion-parameter training you need at least an A100 or RTX 4090. The repo includes a full GPU compatibility table so you know exactly what's possible on your hardware. Includes a complete SFT and RLHF guide as a separate notebook for taking your trained model further. Key capabilities: • End-to-end pipeline: data download → preprocessing → training → text generation • Full transformer implementation from scratch with PyTorch • Trains models from 13M to 2B+ parameters on a single GPU • Training data from The Pile (825GB, 22 diverse datasets) • Tokenization via tiktoken (r50k_base) • SFT and RLHF guide included 100% open source. I've shared the link in the replies!


AI Engineer Complete Resource Kit 2026 (400+ resources): docs.google.com/spreadsheets/d… Like & repost for others!
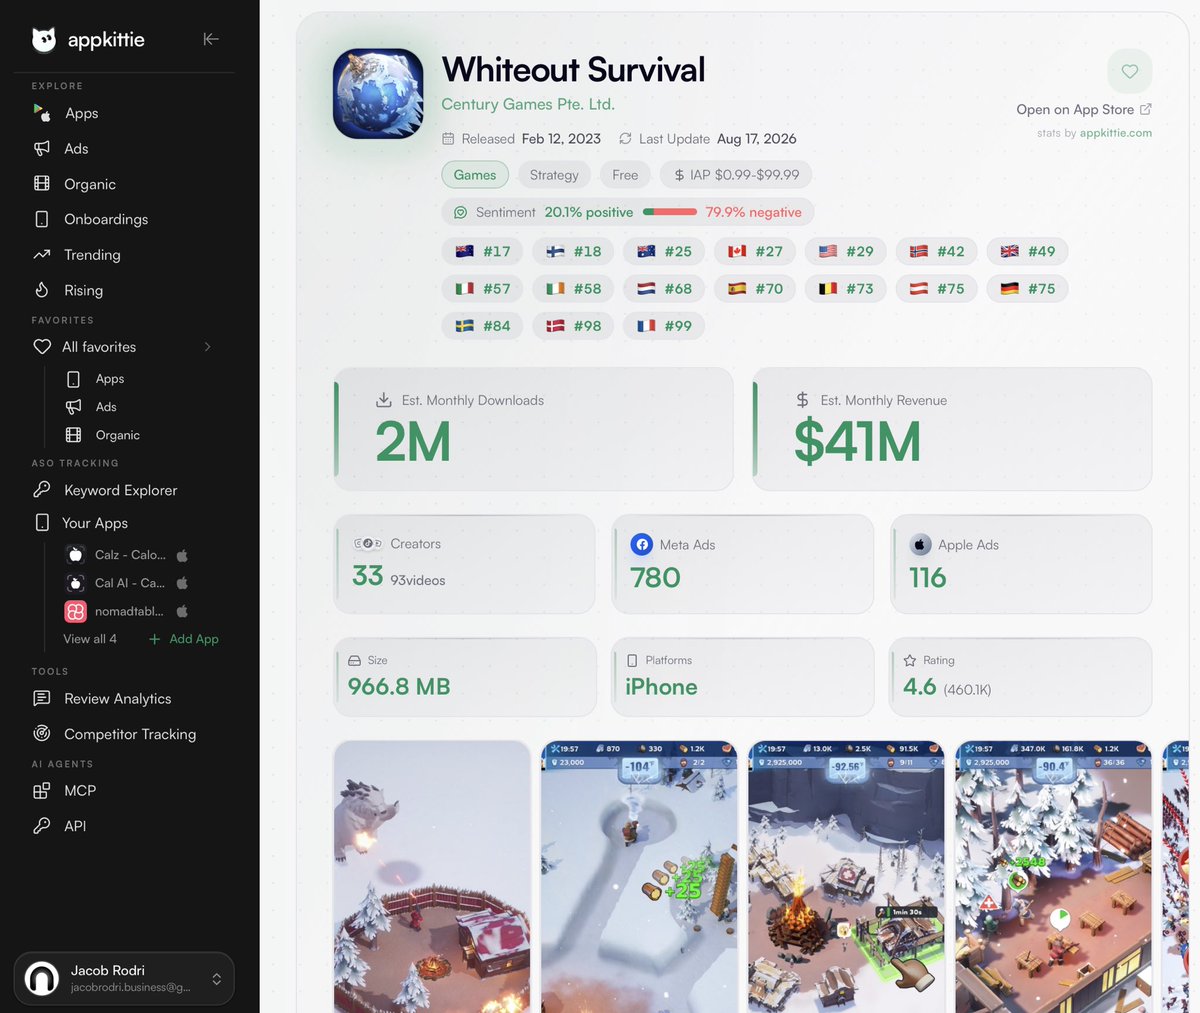
$41,000,000/month💀 it’s insane how much money survival mobile games make

An absolutely brilliant textbook "Foundations of Large Language Models" by Tong Xiao and Jingbo Zhu (2025) is now in @ChapterPal's collection. This book is a comprehensive, technically grounded treatment of modern generative language models for artificial intelligence researchers, engineers, and advanced students in natural language processing. Assuming a foundational background in deep learning, probability, and standard neural sequence modeling, the book explains the entire lifecycle of foundation models—from raw data pre-training and architectural design to alignment, inference acceleration, and system-level scaling. It's a great in-depth read specifically on Large LMs after my The Hundred-Page Language Models Book that covers neural network and deep learning basics, count-based LMs, RNNs, and transformers. Read the book with an AI tutor: chapterpal.com/ebook/14fa0543… (All books on ChapterPal are free to read with a free account.) The book has 76 beautiful illustrations across 277 pages. Table of contents: Preface Notation 1. Pre-training - 1.1. Pre-training NLP Models * 1.1.1 Unsupervised, Supervised and Self-supervised Pre-training * 1.1.2 Adapting Pre-trained Models - 1.2. Self-supervised Pre-training Tasks * 1.2.1 Decoder-only Pre-training * 1.2.2 Encoder-only Pre-training * 1.2.3 Encoder-Decoder Pre-training * 1.2.4 Comparison of Pre-training Tasks - 1.3. Example: BERT * 1.3.1 The Standard Model * 1.3.2 More Training and Larger Models * 1.3.3 More Efficient Models * 1.3.4 Multi-lingual Models - 1.4. Applying BERT Models - 1.5. Summary - References 2. Generative Models - 2.1. A Brief Introduction to LLMs * 2.1.1 Decoder-only Transformers * 2.1.2 Training LLMs * 2.1.3 Fine-tuning LLMs * 2.1.4 Aligning LLMs with the World * 2.1.5 Prompting LLMs - 2.2. Training at Scale * 2.2.1 Data Preparation * 2.2.2 Model Modifications * 2.2.3 Distributed Training * 2.2.4 Scaling Laws - 2.3. Long Sequence Modeling * 2.3.1 Optimization from HPC Perspectives * 2.3.2 Efficient Architectures * 2.3.3 Cache and Memory * 2.3.4 Sharing across Heads and Layers * 2.3.5 Position Extrapolation and Interpolation * 2.3.6 Remarks - 2.4. Summary - References 3. Prompting - 3.1. General Prompt Design * 3.1.1 Basics * 3.1.2 In-context Learning * 3.1.3 Prompt Engineering Strategies * 3.1.4 More Examples - 3.2. Advanced Prompting Methods * 3.2.1 Chain of Thought * 3.2.2 Problem Decomposition * 3.2.3 Self-refinement * 3.2.4 Ensembling * 3.2.5 RAG and Tool Use - 3.3. Learning to Prompt * 3.3.1 Prompt Optimization * 3.3.2 Soft Prompts * 3.3.3 Prompt Length Reduction - 3.4. Summary - References 4. Alignment - 4.1. An Overview of LLM Alignment - 4.2. Instruction Alignment * 4.2.1 Supervised Fine-tuning * 4.2.2 Fine-tuning Data Acquisition * 4.2.3 Fine-tuning with Less Data * 4.2.4 Instruction Generalization * 4.2.5 Using Weak Models to Improve Strong Models - 4.3. Human Preference Alignment: RLHF * 4.3.1 Basics of Reinforcement Learning * 4.3.2 Training Reward Models * 4.3.3 Training LLMs - 4.4. Improved Human Preference Alignment * 4.4.1 Better Reward Modeling * 4.4.2 Direct Preference Optimization * 4.4.3 Automatic Preference Data Generation * 4.4.4 Step-by-step Alignment * 4.4.5 Inference-time Alignment - 4.5. Summary - References 5. Inference - 5.1. Prefilling and Decoding * 5.1.1 Preliminaries * 5.1.2 A Two-phase Framework * 5.1.3 Decoding Algorithms * 5.1.4 Evaluation Metrics for LLM Inference - 5.2. Efficient Inference Techniques * 5.2.1 More Caching * 5.2.2 Batching * 5.2.3 Parallelization * 5.2.4 Remarks - 5.3. Inference-time Scaling * 5.3.1 Context Scaling * 5.3.2 Search Scaling * 5.3.3 Output Ensembling * 5.3.4 Generating and Verifying Thinking Paths - 5.4. Summary - Appendix - References

Beginner-friendly LLM course exploring foundations, architectures, training, deployment, and current trends: tinyurl.com/vp844fsm v/@Hesamation

A Stanford professor took two average stocks, rebalanced them daily, and turned $100,000 into $7 million without predicting a single price. Bookmark & watch today, no matter what.

Guy lives the most interesting indie career I've ever seen 👏👏👏

I’ll be paid $103,000 to race so far. I’m going to bed now, let’s see what gets tattooed on my body tomorrow! Auction ends in 6 hours btw.

AI/ML Series (Lesson 6/100): RAG projects that actually land interviews. -- Foundation Level -- Document Analysis with LLMs → Process PDFs instantly → Extract key insights → lnkd.in/dvPehYtB First RAG System → Build from scratch → No frameworks needed → lnkd.in/dRq4NnCm IBM RAG Guided → Step by step → Production patterns included → lnkd.in/dgTz_Av6 -- Advanced Techniques -- GraphRAG Pipeline → Knowledge graph retrieval → Smarter context understanding → lnkd.in/dNmynkGZ Multi Document RAG → Query across sources → Unified retrieval logic → lnkd.in/dEj8478y Agentic RAG Pipeline → Autonomous decision making → Tool calling integrated → lnkd.in/gXWsJYXT Real Time Assistant → LangChain powered system → Live data retrieval → lnkd.in/gbHjG7Df AI Research Agent → Automate paper analysis → Smart summarization built-in → lnkd.in/dec__v4e Multimodal RAG System → Text and images → IBM guided tutorial → lnkd.in/d6UwUX3z LangChain RAG Agent → Production ready architecture → Memory and tools → lnkd.in/drdmzwg6 Master these 10 projects. You're building intelligent systems not just writing code. Save for later. Repost ♻️ for AI builders.

AI/ML Series (Lesson 5/100): AI Agent Project Structure 🤖 Building an AI agent is not just about connecting an LLM to a prompt. As the project grows, you need a clean structure so you can add tools, memory, APIs, models, and tests without turning the codebase into a mess.

《Build an AI Agent (From Scratch)》:manning.com/books/build-an… Manning的新书,阐述如何在不使用外部框架的情况下,从设计到部署逐步构建一个实验性的Python代理。


so many cool classes coming up in the fall quarter! - Deep Learning Alchemy by @kothasuhas @tatsu_hashimoto @wen_kaiyue : deep-learning-alchemy.github.io - Engineering AI Agents by @Diyi_Yang @michaelryan207 @jyangballin : cs329z.stanford.edu - AI Agents by @gneubig @dan_fried : cmu-agents.com - World Models by @thoma_gu : cis.upenn.edu/~cis6280/ have fun learning my friends

this is pure f*cking treasure how to build your first ai agent (full walkthrough) a year ago this would have saved me two weeks. my first agent would've shipped the same afternoon in the right hands it changes what one person can ship alone:
Computer scientists discover the power of *closed loop* and *error correction*! I have advocated for many years by now that all intelligent systems would be closed-loop, not open end-to-end. This has been the very basic lesson from Cybernetics (control theory and systems theory), originated more than 80 years ago. This view has been prominently featured in our open-sourced new book about the principles of intelligence: ma-lab-berkeley.github.io/deep-represent…

前 Scale AI 创始人、刚出任 @Meta 首席 AI 官的 @alexandr_wang ,在 YC 现场跟 @garrytan 对谈时抛出这枚深水炸弹,直接把全网的技术管理层给听沉默了。 他说在 Meta 内部,我们已经真实看到了这种情况: 只要设计出正确的智能体循环(Agentic

this paper is f*cking insane it analyzed 56,000 trading strategies and found something brutal: over 40% looked strong in-sample out-of-sample, the average Sharpe collapsed to basically zero the framework is ruthless: test on unseen data add real costs check regime robustness assume high Sharpe can come from luck the crazy part is that testing 10,000 random strategies can produce a Sharpe above 2.0 purely by chance and after frictions, the median Sharpe in the sample fell from 1.23 to 0.08 most traders search for the strategy with the highest backtest real quants search for the one that still exists after reality touches it bookmark before this thread gets buried


Inference roadmap I gotta follow: 1) Watch this course fully : youtube.com/playlist?list=… (Covers everything related to LLM Inference+ Training but on high level) 2) Gonna read this resource: jax-ml.github.io/scaling-book/ ( for deep dive on topics) 3) Read PMPP(CUDA & GPU specific chapters) 4) Blogs and codebase of vLLM , SGlang, llama.cpp 5) Inference Engg by philip book for brush up on the concepts 6) Also these notes which i found randomly on X for brushup: x.com/gauri__gupta/s… Along with it : contributions to the above mentioned repo for understanding depth + talking with folks building in inference here


Domesticated Brain @rasangarocks
71K Followers 78K Following This is the official twitter account for web site called Domesticated Brain. We are sharing various kinds of #computer #tutorials and latest #technology news.
Prem Palhade @premwomp
3K Followers 7K Following cs @ vit, 5x hack winner, prev @iitbombay, not sus games
Olivia Freire @freire_oli61495
383 Followers 7K Following No menosprecies a nadie, trata a todos por igual 🇲🇽🇺🇸

சிங்கம்... @Singamonfire
14K Followers 13K Following சின்ன சின்ன அன்பில்தானே ஜீவன் இன்னும் இருக்கு || Belongs to #ஒன்றியஉயிரினங்கள் Dravidian Stock || எங்க வண்ணம் 🖤❤️
Grow More @GrowMoreTogther
5K Followers 6K Following Meaningful conversations. Real connections. Shared growth.
Allan Ignatius VP @AlanIgnatius
14K Followers 15K Following Short Break | Less Active | Focused on Work | DM Open
Hyena 💫🥂✨ @Hyena_Hyena1
11K Followers 8K Following வாழ்க்கையில் பல துன்பம் இருந்தாலும் அதை ஒர் ஓரம் வைத்து, ஓடிக்கொண்டிருக்கும் ஒரு பிறவி மகிழ்ச்சி புன்னகை, பிறரை சிரிக்க வைக்கும் குணம் இருக்கு பாத்துக்கலாம் 💪
Mason, Versluis. @maassonversluis
326 Followers 7K Following Internet Entrepreneur, Creator & Crypto Investor. 7 years in crypto. Passionate. opinions, not financial advice…
Dayyib Sanka @Dayyib_19
123 Followers 483 Following only private elite here!! I will mainly talk abou crypt market $ICP, price action analysis etc. ONLY FOR A FEW PEOPLE MAIN ACCOUNT @Dayyib19
Montana @MontanaMMXMS
70 Followers 615 Following only private elite here!! I will mainly talk abou crypt market $ICP, price action analysis etc. ONLY FOR A FEW PEOPLE MAIN ACCOUNT @MontanaMMXM
花束/✨ @BeqrBullTrqder_
94 Followers 2K Following
. ✪ @TempojCT
417 Followers 4K Following Trading ICT Concepts | Teaching People How I Made 33k/m With The IFVG Model

Amir khan Khoso @AmirkhanKh8247
752 Followers 7K Following FOR ACCOUNT MANAGEMENT JOIN OUR TELEGRAM CHANNEL

Wood Fx @PubgF40317
950 Followers 8K Following I am Professional Trader My 7 Year's experience in Forex Trading
Perseus @KerstinNil53285
672 Followers 3K Following ICT | MMXM | chasing mastery not perfection. partnered @FTmarkestlive | use code PERSEUS for max discounts
الامان فورک... @MuhammadHa70835
344 Followers 6K Following Allah plans are better than our desires. I am Professional Forex Trader account Manager We are providing good signals everyday.
Shahzeb Khan @ShahzebKha55815
108 Followers 1K Following #XAUUSD #GOLD Join my telegram channel for free signals👇
Devri Fx @DevriF23160
101 Followers 1K Following
Michael @FxMlcro28559
72 Followers 1K Following #XAUUSD #gold Get 3–4 free trading signals daily Get here 👇🏻👇🏻 https://t.co/JqwpYRezGG
gale Fx @muzammilub54
725 Followers 7K Following I am Professional Trader My 7 Year's experience in Forex Trading

Xi Lee | 希李 🐳�... @XiLeeTrades
255K Followers 68K Following Crypto trading & wallet tracking. Love using AI, and coding on the side.

Crypto ShieldScript @ISAYAKUHODANGA
3K Followers 939 Following Market Analysis | Trader Crypto & Forex | PA | ICT | SMC Sharing Market Value. This is educational information only. Trading involves significant risk of loss
Katie @DarknessKatie
4K Followers 5K Following
The Trading Geek (Bra... @Bradgohtrades7
207 Followers 2K Following only private elite here, I will mainly talk about crypto market, price action analysis etc. only for a few people main account @Bradgohtrades
Milind S @milindlabs
4K Followers 668 Following Check out https://t.co/TpQZ5WbUtE and https://t.co/Lw6IDgUqBR and https://t.co/CIM33zj0AD
video🍼call @Videocall96
2K Followers 46 Following 🙋♂️Hi I'm bad 👇 Stay away from the good ones There's no point in being polite From today I'm rude If you like me, like and follow and send me a message 🫣👈
Kin @KinGao476942
3K Followers 500 Following SpaceXAI 官方认证大使;Grok bot 重度患者,专注研究AI 和自媒体;接AI企业培训/顾问,199 进答疑群➕V:15917166191
Diogo Almeida @CompleteSkeptic
142K Followers 94 Following Sane + 🌶️ takes in an insane AI world... AI capabilities researcher: co-created RLHF/ChatGPT @ @openai now trying to right the wrong 🤭 (ceo @typesafeai)
sauda moni @sauda_coder
17K Followers 60 Following 📧 [email protected] 📧 AI Growth Specialist | Helping AI tools, websites & founders grow on X | 400+ AI tools reviewed | DM for Ads,Promos and collabs🛑
Public Exhibitions @PubExbhibition
85K Followers 0 Following
マネージャー @yusufgorgulu570
3K Followers 505 Following
Grandfather intimate ... @Grandfathervid1
84K Followers 0 Following
Mayor. @BIGMayrr
7K Followers 2K Following Building & sharing AI agents + OSS tools Daily finds that actually ship Dm for partnership [email protected] 📩
Harsh shekhawat @wordofshekhawat
5K Followers 2K Following Tweets with a pinch of humour and sarcasm CRICKET || MOVIES || GTA V1 ||
@Xx-Korean @Xxkorean__8
181K Followers 0 Following
只发极品AV @Sari1014Ren
234K Followers 9 Following
kartikey singh @askwhykartik
15K Followers 708 Following Helping founder build mvp fast https://t.co/IOeZzcya4s ($100k), building consumer apps
Clash || Clash.dev @Clash22786
484 Followers 265 Following 17 | Just a student learning to code Python | GO | future Backend Dev

Mertcandemirr67 @mertcandemirr67
15K Followers 1K Following
Tony Centrino @CentrinoTo14620
35K Followers 456 Following Loving husband of a hot wife. Sharing is caring. Kinky and kind. No mercy in bed.

Arham ul 🇧🇩 @arhamul1241
22K Followers 2K Following bull from dhaka. টেলিগ্রাম : @siq10987 interfaith, mom,aged mohila,putki boro damri fav amr
Beach @oicomebaby
97K Followers 0 Following
CelebratiesDressed/Nu... @Celebsfever
199K Followers 531 Following Your daily source of hottest celebraties pics/vids | daily uploads | I don't own any of pics and videos | DM for content removal |
Celebs Uncensored @CelebsUncensord
91K Followers 0 Following
Core studios @koreanpea_
41K Followers 28 Following
Aliihere @rwpsexymate
24K Followers 16 Following Open-minded | Friendly | Here to meet interesting people and couples
Premium Vault @Premiiumlt
130K Followers 0 Following
Jacob Rodri @jacobrodri_
40K Followers 497 Following founder https://t.co/JVdPBQGEBb - find winning apps, replicate what's working. tweets about growth and my learnings🫡
Fill Up My Stepmom �... @stepmom_up
185K Followers 0 Following
Siddharth @Pseudo_Sid26
6K Followers 2K Following ML-DL | 22 | Solving memory 4 agents | Applied AI eng (US) | Prev: @ filmple (EU) | AI eng @ miracleai | ML Lead @ datraai | 6x :🏆| Professional Music Producer
Vikram @msharmavikram
4K Followers 661 Following @NVIDIA Sr. Research Scientist | UIUC PhD All opinions and tweets are personal. Tweets about AI Inference, CUDA and GPU systems.
Family With Mom @Familyxxd
108K Followers 0 Following
Jav Code @JavCodeLust
677K Followers 0 Following Dm For Promotions. +🔞 CONTENT IS SHARED. SUITABLE FOR THOSE OVER 18 YEARS OF AGE Click the link for more content. 👇
เฮียขี้... @Tidmhee16v1
67K Followers 108 Following ลงไว้เป็นแนวทางสำหรับผู้ชายขี้เหงา ความเห็นส่วนตัว แบ่งปันกัน อย่าให้พวกมิจมาหลอกได้ มีเงินต้องมีสมองด้วย

Dr. Xia Khan @DrXiakhan
37K Followers 25K Following Saving lives by profession, changing lives by passion. 🩺
Corrupted soul @2211_soul
9K Followers 21 Following
Orgy Swingers @Orgyswingers0
115K Followers 0 Following

MILF Lover @CrazyBoy1609
74K Followers 232 Following

Fun in Taxi @Taxifuns
106K Followers 0 Following what happen behind closed doors stay behind close doors

Andrew Gazdecki @agazdecki
315K Followers 7K Following Founder and CEO of @acquiredotcom. https://t.co/wRMIssDmhl has helped 1000s of startups get acquired and facilitated $500m+ in closed deals.
Danielle @dinkydani21
23K Followers 738 Following Bootstrapped nomad for 9+ years 🎒 in 60+ countries 🗺️ w/ @jamesivings Unsubscribe from emails 💌 https://t.co/8TZvCY6KbW
Sveta Bay @sveta_bay
36K Followers 296 Following
Nathan Barry @nathanbarry
151K Followers 2K Following Founder & CEO at @Kit - the operating system for creators who mean business: https://t.co/EiINcevRbX
Brett @BrettFromDJ
171K Followers 273 Following Running a $1M one-man design studio. 🙂 https://t.co/Bd698tQuPG: $100K MRR ✍️ https://t.co/qtdiuMzBWh: $12K MRR // Building https://t.co/kbOZ647RU8 & https://t.co/DEmnafGhWg
Adam Pietrasiak @pie6k
39K Followers 574 Following I design through code. Building https://t.co/6ceZFejl4s (@screenstudio). Support → please reach out at [email protected] instead of DMs.
Arvid Kahl @arvidkahl
210K Followers 18K Following Building https://t.co/od97B0ItgS and https://t.co/6pSdm6nybd in Public. Raising all the boats with kindness. 🎙️ https://t.co/6w69DZmPYf · ✍️ https://t.co/lpnor5s0Ju
Trends for United States
You might like


















